Technology
What Is an Electrical Muscle Stimulation Device and How Does It Work?

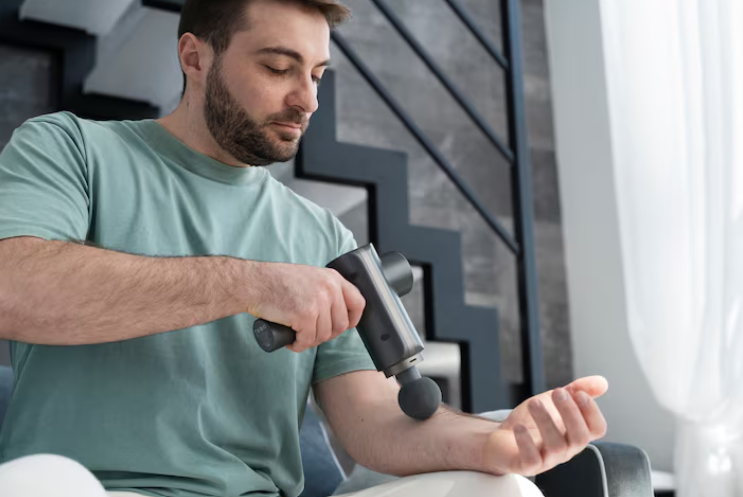
In recent years, technology has transformed the way people approach fitness, recovery, and muscle rehabilitation. Among the innovations gaining attention are electrical muscle stimulation (EMS) devices, which are widely used by athletes, fitness enthusiasts, physical therapists, and individuals seeking muscle recovery support. As more Americans look for convenient ways to complement their workout routines, electrical muscle stimulation devices have become increasingly popular.
But what exactly is an EMS device, and how does it work? Understanding the science behind this technology can help users make informed decisions about incorporating it into their wellness and fitness routines.
Understanding Electrical Muscle Stimulation
Electrical Muscle Stimulation (EMS) is a technology that uses low-level electrical impulses to trigger muscle contractions. These impulses mimic the natural electrical signals sent by the brain through the nervous system to activate muscles.
An EMS device typically consists of a control unit connected to electrode pads that are placed on the skin over specific muscle groups. When activated, the device sends electrical pulses through the electrodes, causing the targeted muscles to contract and relax repeatedly.
This process can be used for various purposes, including:
- Muscle strengthening
- Recovery after exercise
- Improving circulation
- Muscle re-education after injury
- Reducing muscle soreness
- Supporting physical therapy programs
Today, many fitness professionals and rehabilitation specialists use electrical muscle stimulation machines as part of comprehensive training and recovery strategies.
The Science Behind EMS Technology
To understand how EMS works, it helps to know how muscles naturally function.
When you decide to move a muscle, your brain sends electrical signals through motor neurons to the muscle fibers. These signals tell the muscles when and how strongly to contract.
An EMS device bypasses the brain’s signaling process by delivering controlled electrical impulses directly to the muscle. As a result, the muscle contracts even when the user is not actively performing a physical movement.
The contractions generated by EMS can vary in intensity, frequency, and duration depending on the device settings and intended purpose. Lower frequencies are often used for recovery and relaxation, while higher frequencies may be used for muscle conditioning and strengthening.
Types of EMS Devices
The market offers several types of EMS devices designed for different applications.
Fitness EMS Devices
These devices are commonly used by athletes and fitness enthusiasts to supplement traditional exercise routines. They target muscle groups such as the abdomen, arms, legs, glutes, and back.
Rehabilitation EMS Devices
Physical therapists often use EMS devices to help patients recover from injuries or surgeries. They may assist in restoring muscle function, preventing muscle atrophy, and improving mobility.
Portable Home-Use Devices
Compact and user-friendly EMS units allow individuals to perform sessions at home. These devices have become increasingly popular among people seeking convenient recovery and muscle activation solutions.
Many modern electrical muscle stimulation machines offer customizable programs that allow users to adjust intensity levels according to their goals and comfort.
Common Uses of Electrical Muscle Stimulation Devices
1. Muscle Strengthening
EMS can help activate muscle fibers that may be difficult to engage during traditional workouts alone. When combined with regular exercise, EMS may contribute to improved muscle conditioning and performance.
2. Post-Workout Recovery
After intense exercise, muscles often experience fatigue and soreness. EMS devices can stimulate blood flow and gentle muscle contractions that may support the recovery process.
Athletes frequently use EMS sessions after training to help reduce muscle stiffness and promote relaxation.
3. Physical Rehabilitation
Following injuries, surgeries, or periods of inactivity, muscles can weaken due to reduced use. EMS is often incorporated into rehabilitation programs to help maintain muscle activity and support recovery under professional guidance.
4. Improved Circulation
The repeated contractions produced by EMS can encourage blood circulation in targeted areas. Improved circulation may help deliver oxygen and nutrients to muscles while supporting recovery processes.
5. Muscle Re-Education
Certain medical conditions or injuries can affect muscle control. EMS may be used as part of therapeutic programs to help retrain muscles and improve neuromuscular function.
What Happens During an EMS Session?
Using an EMS device is relatively straightforward.
- Electrode pads are placed on the desired muscle group.
- The device is turned on and adjusted to an appropriate intensity level.
- Electrical impulses begin stimulating the muscles.
- Users experience rhythmic contractions and relaxations of the targeted muscles.
- Sessions typically last between 15 and 30 minutes, depending on the program and objective.
Many users describe the sensation as a tingling or pulsing feeling that becomes stronger as intensity increases. While muscle contractions can feel unusual initially, they should not be painful when used correctly.
Benefits of EMS Technology
Convenience
One of the biggest advantages of EMS devices is their convenience. Users can target specific muscle groups while at home, making it easier to incorporate recovery sessions into busy schedules.
Targeted Muscle Activation
EMS allows users to focus on individual muscle groups with precision, which can be beneficial for rehabilitation and performance enhancement.
Complements Traditional Exercise
EMS is not intended to replace exercise but can complement a well-rounded fitness program by providing additional muscle stimulation.
Customizable Programs
Modern electrical muscle stimulation machines often include multiple settings for strength training, endurance, recovery, relaxation, and rehabilitation.
Non-Invasive Technology
EMS devices offer a non-invasive approach to muscle stimulation without requiring medication or surgical intervention.
Are EMS Devices Effective?
Research suggests that EMS can be effective when used appropriately and consistently. Studies have shown benefits in areas such as muscle activation, rehabilitation, and recovery support.
However, it’s important to understand that EMS is most effective when combined with healthy lifestyle habits, including:
- Regular exercise
- Proper nutrition
- Adequate hydration
- Sufficient sleep
- Consistent recovery practices
While EMS can provide valuable support, it should not be viewed as a standalone solution for fitness or weight loss goals.
Safety Considerations
EMS devices are generally considered safe when used according to manufacturer guidelines.
However, users should take certain precautions:
- Follow all instructions provided with the device.
- Start with lower intensity levels.
- Avoid placing electrodes over the heart, neck, or damaged skin.
- Consult a healthcare professional if you have a medical condition.
- Do not use EMS devices if you have certain implanted medical devices unless approved by your doctor.
Pregnant individuals and those with specific medical concerns should seek professional medical advice before using EMS technology.
Choosing the Right EMS Device
When selecting an EMS device, consider the following factors:
Adjustable Intensity Levels
A device with multiple intensity settings allows you to customize treatments according to your comfort and goals.
Program Variety
Look for devices that offer different modes for recovery, strength training, endurance, and relaxation.
Electrode Quality
High-quality electrode pads improve comfort, conductivity, and durability.
Portability
Portable EMS units make it easier to use the device at home, at the gym, or while traveling.
User-Friendly Controls
An intuitive interface can enhance the overall user experience and make sessions more efficient.
Final Thoughts
Electrical muscle stimulation technology has evolved significantly over the years, becoming a valuable tool for fitness, recovery, and rehabilitation. By using controlled electrical impulses to stimulate muscle contractions, EMS devices help support muscle activation, circulation, and recovery efforts.
Whether you’re an athlete looking to optimize performance, someone recovering from physical strain, or simply interested in innovative wellness technologies, electrical muscle stimulation machines can be a useful addition to your routine when used correctly. Understanding how these devices work and choosing a quality product can help you maximize the potential benefits while supporting your overall health and fitness goals.

AI search is changing how people discover and evaluate brands. Instead of scanning a page of search results, someone can ask an AI assistant a direct question and receive a short answer that summarizes products, companies, competitors, or recommendations.
That creates a new problem for businesses: information about a brand has to remain clear and consistent as it is collected, interpreted, and presented by different AI systems.
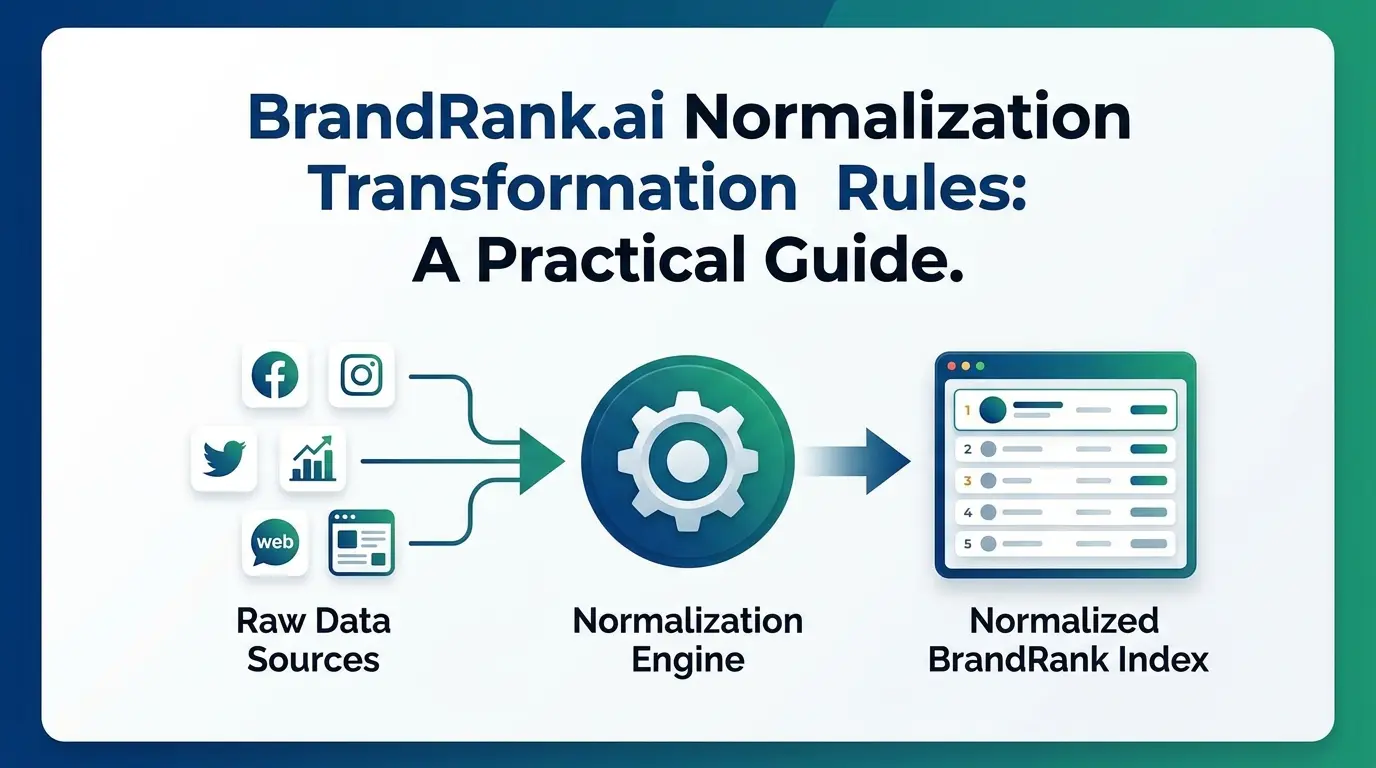
This is where the idea behind BrandRank.ai normalization transformation rules becomes useful. While BrandRank.AI publicly focuses on AI visibility, claim verification, content readiness, citations, and recommendation share, the broader concept of normalization and transformation is about making brand information consistent enough to analyze and interpret reliably.
What Does BrandRank.ai Normalization Mean?
Normalization generally means taking information that appears in different formats and bringing it into a consistent structure.
For example, a company might appear online as:
- ABC Technologies Inc.
- ABC Technologies
- ABC Tech
- abc-technologies.com
A human can usually understand that these references may point to the same organization. A data system, however, benefits from consistent identifiers and clearly structured information.
In an AI brand-monitoring environment, normalization can help make information easier to compare across prompts, sources, platforms, and time periods.
The goal isn’t to make every source identical. It is to reduce unnecessary differences that can make brand information harder to interpret.
What Are Transformation Rules?
Transformation rules describe how information is changed from one format or representation into another.
A simple example would be turning:
“ABC Technologies, Inc.”
into a standardized company name such as:
“ABC Technologies”
Another transformation might convert several variations of a product category into one consistent category label.
These transformations can be useful when a system needs to compare information collected from different websites or AI-generated answers.
The important distinction is that normalization creates consistency, while transformation defines how the data gets from one representation to another.
Why Does This Matter for AI Search?
AI answer engines don’t simply display a list of matching pages. They can combine information from multiple sources and produce a synthesized response.
BrandRank.AI describes its platform as testing priority queries across major AI platforms, capturing generated answers, identifying cited sources, and extracting key claims.
That means businesses need to think beyond traditional keyword rankings.
Consider a customer asking:
“What are the best software companies for small businesses?”
The answer may depend on how different sources describe each company, what claims are supported, and whether those descriptions are consistent.
If one source calls a company a “CRM platform,” another calls it “business automation software,” and a third describes it as “sales management software,” the differences may be harmless. But when important facts conflict, the resulting AI answer can become less predictable.
Common Normalization Rules to Consider
There isn’t a single universal set of normalization rules that applies to every AI system. However, several practical rules can make brand information easier to interpret.
1. Standardize Brand Names
Choose one official brand name and use it consistently across important pages.
That doesn’t mean every third-party website must use exactly the same wording. It simply gives search and AI systems a clear reference point.
2. Keep Product Names Consistent
Product names should not change randomly from one page to another.
If a product has an official name, use that name consistently in product pages, documentation, FAQs, and other important content.
3. Separate Facts From Marketing Language
Statements such as “the world’s leading platform” are different from measurable facts such as a product’s release date or supported features.
Clear factual information is easier to verify than vague promotional claims.
4. Use Structured Information
Organization details, product information, FAQs, and other important entities should be presented in a clear structure.
BrandRank.AI’s public material specifically discusses content structure, schema, citation strength, and content readiness as parts of AI visibility.
5. Preserve Important Context
Transformation should not remove information that changes the meaning of a claim.
For example, changing:
“Available in the United States”
to:
“Available worldwide”
wouldn’t be a harmless formatting change. It would alter the underlying claim.
Good transformation preserves meaning.
A Simple Example
Imagine a fictional company called Northstar Analytics.
Its website says:
Northstar Analytics provides analytics software for mid-sized retailers.
A business directory describes it as:
Northstar Analytics — retail analytics platform.
A news article calls it:
Northstar, a data analytics company.
These descriptions are different, but they share an underlying concept.
A useful normalization process could identify:
Brand: Northstar Analytics
Category: Analytics software
Primary market: Retail
Target customer: Mid-sized businesses
The transformation step can then map different descriptions into a consistent analytical structure without pretending that every source used identical wording.
Normalization Does Not Mean Changing the Truth
This is probably the most important point.
A normalization process should make information more consistent, not make inconvenient information disappear.
If two reliable sources disagree, the solution isn’t simply to transform one of them until they match.
Instead, the disagreement should remain visible and be investigated.
This matters particularly for AI-generated answers because BrandRank.AI’s public platform emphasizes identifying inaccurate, outdated, disputed, or unsupported claims and tracing information back to its sources.
How Transformation Rules Can Help With AI Visibility
AI visibility is not simply about mentioning a brand as many times as possible.
BrandRank.AI describes AI visibility in terms of whether and how a brand is cited in generated answers, while its broader framework also considers visibility, vulnerability, and content readiness.
Consistent information can therefore support several practical areas:
- clearer entity identification
- easier comparison between sources
- fewer conflicting descriptions
- better organization of product information
- stronger content consistency
- easier verification of important claims
These are useful foundations, but they should not be confused with a guaranteed method for making an AI system recommend a particular brand.
What Should Businesses Review?
If you’re trying to improve how your company is represented in AI search, start with the basics.
Check your brand name
Is the company name consistent across your website and important third-party profiles?
Check your core descriptions
Can someone quickly understand what the company actually does?
Check your product information
Are product names, features, pricing information, and availability described consistently?
Check important claims
Can major claims be supported by credible sources?
Check third-party references
Do reputable websites describe the company accurately?
Check outdated information
Old product pages, discontinued services, outdated company descriptions, and old announcements can continue to influence how a brand is understood.
Normalization vs. Traditional SEO
Traditional SEO often focuses heavily on keywords, rankings, links, and search-result visibility.
AI search adds another layer: how information about an entity is interpreted and represented in an answer.
BrandRank.AI itself distinguishes traditional SEO from AI search optimization, noting that AI systems generate answers rather than simply presenting a list of pages.
That doesn’t make traditional SEO irrelevant. Strong technical SEO, useful content, crawlability, and authoritative sources still matter.
The difference is that businesses now have another representation problem to solve: not only “Can people find our page?” but also “Is the information about our brand clear and accurate when AI summarizes it?”
A Practical Workflow
For a simple starting process, businesses can use five steps:
1. Collect
Gather important brand information from your website and major external sources.
2. Normalize
Identify different names, categories, product labels, and descriptions that refer to the same entities.
3. Transform carefully
Create consistent representations without changing the meaning of factual claims.
4. Verify
Check important claims against reliable sources.
5. Monitor
Test how AI systems represent the brand over time.
This last step matters because AI answers can change. BrandRank.AI says it runs daily testing across prioritized queries and multiple AI platforms, which reflects the broader need for ongoing monitoring rather than a one-time optimization exercise.
Final Thoughts
The phrase BrandRank.ai normalization transformation rules points to an important issue in AI-driven brand visibility: information needs to be consistent enough to analyze, but transformation should never come at the expense of accuracy.
Businesses should focus on clear entity names, consistent product information, structured content, verifiable claims, and trustworthy third-party references.
The objective isn’t to manipulate an AI answer. It’s to make the underlying information about a brand clearer, easier to verify, and harder to misunderstand.
As AI becomes a larger part of how people research companies and products, that basic discipline can become just as important as traditional search optimization.
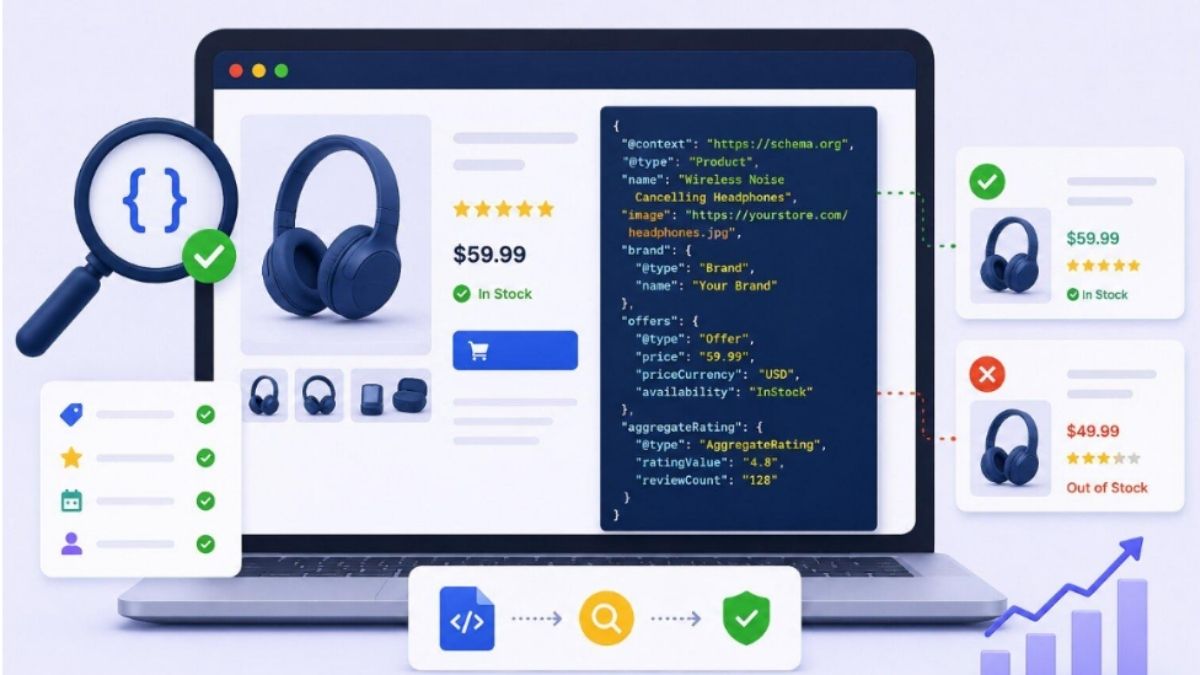
Structured data only works when it tells the truth about what’s actually on the page. A lot of sites carry schema that was accurate six months ago and has drifted since: a price changed, a byline got swapped, an FAQ got trimmed, but the JSON-LD never caught up.
That gap between what a page says and what its markup claims is more common than most site owners realize, and it rarely shows up as an obvious error. Running pages through a schema markup checker is a useful way to catch structured-data issues and identify potential mismatches before they become a larger problem.
This guide walks through what a real mismatch looks like, how to check for one manually, where a checker fits into that process, and how to fix the gaps without breaking rich results that are already working.
What “Matching” Schema Actually Means
Matching schema means the information represented by the markup accurately reflects the content and information visitors can see or verify on the page.
Take a Product page. If the JSON-LD lists a price of $49 but the page itself shows $59, that’s a mismatch. Google expects structured data to accurately represent the content on the page, and misleading or incorrect markup can cause a page to lose eligibility for a rich result.
The same rule applies to review counts, author bylines, publish dates, and FAQ answers. Schema is a promise about what’s on the page. Once that information stops matching reality, search engines may ignore the markup or decline to use it for enhanced search features.
It doesn’t take a redesign to break this promise, either. Someone updates a product price in the CMS, forgets the schema template pulls from a separate field, and the mismatch is live for weeks before anyone notices the rich result is gone.
Why Mismatched Schema Hurts More Than You’d Think
Rich results already earn a real click advantage. Google users click on rich results 58% of the time compared to 41% for non-rich results. Losing that eligibility because of a stale property is a measurable hit to organic traffic.
There’s also a compliance dimension worth taking seriously. Google’s structured data guidelines require markup to represent the content on the page and prohibit irrelevant or misleading structured data. Violations can cause a page to lose eligibility for rich results and, in some cases, can lead to a structured data manual action.
Spotting a Mismatch Manually Before You Automate It
Before reaching for any tool, it helps to know what a manual check actually looks for. It’s slower, sure, but it builds an eye for the patterns a checker will later flag automatically.
That instinct is worth having even after the tooling takes over.
Compare Visible Text Against the JSON-LD Line by Line
Open the page in one tab and the page source in another. Pull up the <script type=”application/ld+json”> block and read it property by property against what’s rendered on screen.
Pay close attention to datePublished, author, price, ratingValue, and reviewCount. These fields can become outdated when content teams make changes without updating the corresponding markup.
Check Field by Field, Not Just Type by Type
It’s easy to confirm the schema type is correct: Article, Product, FAQPage, and stop there. That’s not enough. A Product block can be perfectly typed and still list an availability status that’s months out of date.
Go property by property. If a field doesn’t have a clear match on the page, either update the content or remove the property rather than leaving a guess in place.
Running the Page Through a Schema Markup Checker
Manual review works for one page. It doesn’t scale across a hundred product pages or a blog with years of archived posts, which is where a schema markup checker earns its keep.
What a Good Checker Actually Flags
A solid checker will confirm syntax, catch missing required properties, and show which supported rich result types the page may be eligible for. Google’s own Rich Results Test is a reliable free starting point for validating supported structured data and checking rich-result eligibility.
What It Won’t Catch
No automated checker can tell you that a price in your schema is wrong unless it’s also comparing rendered page content: most tools validate structure, not accuracy. That comparison step still needs a human pass, or a tool built specifically to cross-check visible content against markup.
Common Mismatch Patterns Worth Watching For
Article schema is a frequent offender. Here’s a clean example of what the author and datePublished fields should look like when they’re accurate:
{
“@context”: “https://schema.org”,
“@type”: “Article”,
“headline”: “Example Article Headline”,
“author”: {
“@type”: “Person”,
“name”: “Jane Doe”
},
“datePublished”: “2026-01-15”,
“dateModified”: “2026-07-02”
}
If the byline on the page reads “Content Team” but the schema still says “Jane Doe,” that’s the exact kind of gap a checker catches instantly.
FAQPage schema has its own version of this problem. It’s common to see three FAQ items marked up in JSON-LD while the visible page has been trimmed down to two, or an answer gets rewritten on the page without ever touching the corresponding schema text. Google’s guidelines require the two to match word for word in meaning.
When a JSON-LD Schema Tool Makes More Sense Than Manual Edits
Hand-editing JSON-LD across dozens of templates is where mistakes creep in: a missing comma, a duplicated @type, a property nested under the wrong object. A JSON-LD schema tool that generates markup directly from page fields removes most of that risk, since the schema updates automatically whenever the underlying content does.
This matters most for sites with frequent content changes: e-commerce catalogs, editorial sites with multiple authors, and businesses running seasonal promotions where prices and availability shift often.
Fixing Gaps Without Breaking What’s Already Working
Once a mismatch is found, resist the urge to overhaul the entire schema block. Update only the properties that are actually wrong, then re-test with the Google Search Console Enhancements report to confirm the fix registered correctly.
It’s also worth checking the page against the Schema.org Validator afterward, since syntax errors sometimes get introduced during manual edits even when the intent was correct.
Keeping Content and Schema in Sync Going Forward
Any time page content changes (price, author, FAQ answers, ratings), schema should be part of the same edit, not a separate task someone remembers later or forgets entirely.
Teams that treat structured data as a living part of the page rather than a one-and-done setup are the ones that keep their rich results intact through content updates and platform migrations alike.
Frequently Asked Questions
What happens if schema markup doesn’t match page content?
Google may ignore the structured data, drop existing rich results, or in more serious cases, treat it as manipulative markup, which can affect how the page is indexed.
How often should structured data be audited?
A quarterly check is reasonable for stable pages; e-commerce and frequently updated content should be reviewed monthly or tied directly to the content update process.
Can a schema markup checker fix errors automatically?
Most checkers identify syntax and eligibility issues but don’t rewrite content-accuracy mismatches on their own; those still need a manual comparison or a content-linked generation tool.
Does mismatched schema cause a manual penalty?
Not always, but Google has taken action against sites using structured data to misrepresent content, particularly with review and FAQ schema.
Technology
Why Group Projects and Shared Templates Trigger Plagiarism Flags, and What to Do About It
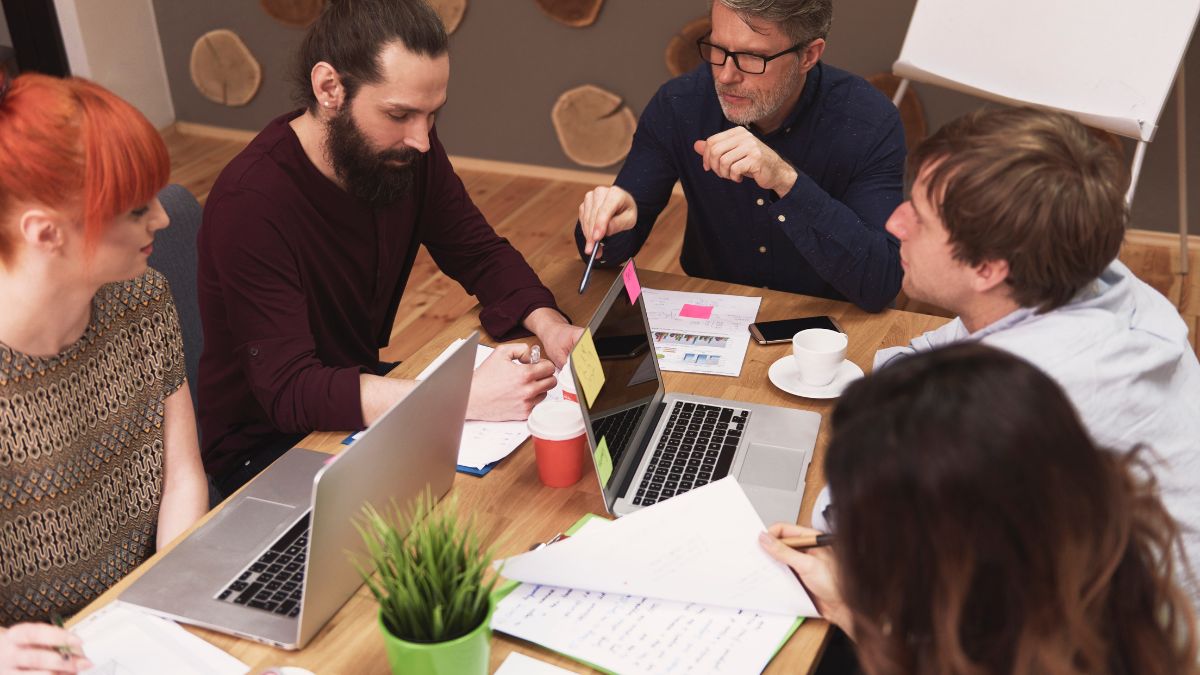
Four students on a group project split the work: one writes the introduction, one the methods section, one the results, one the discussion. Each student runs their own section through a plagiarism checker before the team assembles the final paper. All four come back clean. Then the team submits the combined paper, and the instructor’s institutional checker flags a 22 percent match against another paper submitted by a different team, in a different section, of the same course.
Nobody copied anyone. The overlap came from a shared lab report template the course provided, a standard set of instructions both teams followed closely, and a results section describing the same experiment with the same required variables. This is one of the most common sources of confused, alarmed students in courses that use group work and shared materials, and it has a specific and fixable explanation.
The confusion is compounded by the fact that most students have never seen an unexpected flag like this before and have no framework for distinguishing a legitimate concern from a benign artifact of how the assignment was structured. Understanding the difference matters, both for responding calmly to a flagged score and for structuring group work in a way that keeps the genuinely original sections clearly separated from the shared material.
Where the overlap actually comes from in shared coursework
Courses that provide templates, standardized lab report formats, or required section headings create structural overlap between every student’s submission before anyone writes a single original word. If the assignment instructions specify “include a section titled Materials and Methods that describes X, Y, and Z,” every properly completed submission will share that heading and will likely describe the same required elements in similar language, because the assignment constrains the content.
The lab report problem specifically
Science lab reports are the most common source of this pattern. If 30 students in a chemistry course all ran the same titration experiment, their methods sections will describe the same equipment, the same steps, and the same safety procedures, often using the same standard terminology their textbook or lab manual introduced. A plagiarism checker comparing these 30 reports against each other will find substantial overlap in every pair, and none of it reflects copying between students.
How to tell coincidental structural overlap from actual copying
The distinguishing signal is where the overlap sits and how much of it there is. Overlap confined to standard sections (methods, materials, required headings, boilerplate safety language) with the analysis, discussion, and interpretation sections showing low or no overlap is the signature of coincidental structural matching, not copying. Overlap that extends into the discussion, the analysis of results, or the conclusions is a different and more concerning signal, since those sections should reflect each writer’s independent thinking even when the underlying data or assignment is shared.
A content originality tool that provides a source-by-source breakdown lets you see exactly which sections triggered the match, which is the information that separates a benign structural overlap from a genuine concern. A report showing matches concentrated in the methods section, with the discussion section clean, tells a very different story than a report showing matches throughout.
Group projects add a second layer to this. When multiple students collaborate on one document, their individually written sections will sometimes overlap with each other’s earlier drafts, prior semester submissions the instructor has on file, or with published example papers the course assigned as models. None of these overlaps are plagiarism in the traditional sense, but they can produce alarming-looking scores if the group did not anticipate them.
What to do before submitting shared or templated work
Running a plagiarism check before submission, on the combined final document rather than on each student’s individual section, is the most useful preventive step. Individual sections that check clean can still produce an unexpected combined score once assembled, particularly if different students’ methods sections happen to describe the same shared procedure in similar terms.
Explaining structural overlap proactively
If a score comes back higher than expected and the overlap is concentrated in template-driven or assignment-driven sections, the practical move is to note this proactively rather than waiting for a question. A brief note to the instructor explaining that the methods section follows the required lab template, with a citation to the assigned lab manual, resolves most of these cases before they become a larger issue. Instructors who assign shared templates are generally aware of this pattern and receptive to a clear explanation, provided the explanation is accurate and the discussion and analysis sections show genuine independent work.
For truly original contribution, the fix is not to avoid the shared template (which the assignment usually requires) but to make sure the sections that should reflect independent thinking (analysis, interpretation, discussion, conclusions) are genuinely your own work and read distinctly from your groupmates’ contributions and from other groups working on the same assignment.
Instructors who design courses around shared templates are generally already aware that similarity scores in those courses run structurally higher than in courses without shared materials, and many adjust their expectations or their acceptable-threshold guidance accordingly. Asking the instructor directly what threshold they consider normal for the specific assignment, before submission rather than after a flag, is a reasonable step for any student working with a heavily templated assignment for the first time.
The Shared-Source Trap
Shared templates, standard lab formats, and group assignments all create legitimate overlap that has nothing to do with copying. The key to reading a similarity score correctly in these situations is checking where the overlap sits. Overlap confined to required structural elements is expected and rarely a concern. Overlap in the sections meant to reflect independent thinking is the signal actually worth investigating.
For groups working on shared assignments, running the combined document through Phrasly before submission and reviewing the source-by-source breakdown makes it possible to catch and explain structural overlap before an instructor raises it as a concern.
-
 BLOG1 year ago
hanime1: The Ultimate Destination for Anime Lovers
-
 Technology1 year ago
GLAADVoice.com: How You Can Get Involved and Make a Difference
-
 BILLS1 year ago
Why Does My Instagram Reel Stop Getting Views After One Hour? How to Fix It?
-
 ENTERTAINMENT1 year ago
Crackstreams 2.0: The Future of Free Sports Streaming?
-
 ENTERTAINMENT1 year ago
Sflix: How It’s Changing the Way We Watch Movies and TV Shows
-
 BLOG1 year ago
NHentai.nef: Understanding the Popular Hentai Archive
-
 BLOG1 year ago
ThisVid: What Makes It Stand Out in the World of Online Videos
-
 BLOG1 year ago
Imginn: The Ultimate Tool to View Instagram Content Anonymously